
Abstract
Retrieval-augmented assistants deployed inside organizations answer questions from a permissioned document corpus but forget everything about who is asking. Bolting a conventional per-user memory store onto such a system is insufficient and, worse, unsafe: enterprise knowledge is organizational, not personal; a team’s calibration procedure, a division’s approval policy and an individual’s formatting preference are all “memory,” but they have different owners, different authors, different lifetimes and, critically, different access-control boundaries. This paper presents N-Tier Memory, a memory substrate in which every memory item is indexed by two orthogonal axes: a scope (the tier that owns it: SESSION, USER, GROUP, intermediate organizational tiers, ORG), which doubles as its access-control list, and a kind (preference, authority, procedural, episodic, profile), which determines the direction in which conflicts resolve. We show that scope alone is insufficient: personal preferences must override organizational defaults (nearest-scope-wins) while organizational policy must override personal notes (highest-scope-wins), so the precedence operator must be selected by kind. We further introduce the pointer-not-cache invariant, under which authority memory stores a reference to a versioned source document rather than the value itself, making a class of staleness failures structurally impossible: a compliance requirement, not an optimization, for regulated deployments. The system is realized over infrastructure a permissioned RAG product already runs (PostgreSQL, Qdrant, Redis, Celery) with a deliberately asymmetric storage split: high-churn machine-written personal memory as transactional rows; low-churn human-curated shared memory as version-controlled Open Knowledge Format markdown; both projected into a single ACL-filtered hybrid vector index. We report a four-milestone implementation, a defect taxonomy of five correctness failures found in review (each of which silently defeated a stated guarantee while all tests passed) and their fixes, which we present as ablations. On a live single-tenant deployment the read path adds a warm median of ~124 ms under an 800 ms fail-open deadline, and 12 verification suites covering 60+ individual checks pass against real infrastructure.
Keywords: Agent memory; Retrieval-augmented generation; Access control; Hierarchical scoping; Knowledge management; Enterprise LLM systems
Introduction
A permissioned enterprise assistant is, architecturally, a retrieval-augmented generation (RAG) system with an authorization layer: documents are chunked, embedded and stored in a vector index; a user’s question is embedded; nearest-neighbour chunks are retrieved subject to the asker’s entitlements; and a language model composes a grounded, cited answer. This is a solved and commoditized shape. What such systems conspicuously lack is memory: the assistant knows what the corpus says but nothing about who is asking, what that person has already established, what their team has agreed, or what their organization mandates.
The obvious remedy (attach a per-user memory store) fails on contact with organizational reality for three reasons.
1. Enterprise knowledge is scoped, not personal. “Always answer in metric units” is a property of one employee. “Torque specifications on Line 3 are governed by SOP-114” is a property of a team. “Vendor approvals above the threshold require dual sign-off” is a property of the organization. A flat user-keyed store can represent the first and can only represent the other two by duplicating them into every user, which destroys both authorship and the ability to revoke.
2. Scope alone gives the wrong answer. Suppose the system holds a personal note (“I think the torque is around 20 units”) and a team policy pointer for the same subject. If precedence is a function of scope alone, one fixed direction must be chosen, and either choice is wrong half the time: nearest-wins serves the personal guess over current policy; highest-wins lets an organizational default override an individual’s explicit formatting preference. The direction of precedence must depend on the cognitive type of the memory, not only on its owner. This is the central modelling claim of this paper.
3. Memory that caches facts rots. A memory system that stores “the approval limit is $50k” is correct on the day it is written and silently wrong thereafter. In a regulated deployment (insurance, medical devices, manufacturing compliance) serving a superseded rule is not a quality regression, it is an incident. Memory must be able to point at the versioned source of truth rather than copy it.
Overlaying these is a fourth constraint peculiar to the deployment target: the system ships as a self-contained stack into on-premises, frequently air-gapped, per-customer installations. Every additional stateful service is installed, patched and debugged once per customer, forever. Infrastructure minimalism is therefore a first-class requirement, and it rules out several designs that would be natural in a multi-tenant SaaS setting (§10).
1.1 Contributions
- A two-axis memory model (§3) in which every item carries a scope (which is simultaneously its ACL) and a kind, together with a formal statement of kind-aware precedence: the conflict-resolution operator is selected by kind, so that preference-like memory resolves nearest-scope-wins and authority-like memory resolves highest-scope-wins, with same-scope and pinned tie-breaks specified explicitly.
- The pointer-not-cache invariant (§3.4), enforced at three independent points (extraction-time schema validation, commit-time linting, and read-time resolution), which makes authority staleness structurally impossible rather than operationally unlikely.
- A storage architecture derived from data profile rather than uniformity (§4): personal memory is high-churn, machine-written, concurrent and disposable, so it is stored as independently addressable transactional rows; shared memory is low-churn, human-authored, durable and audit-critical, so it is stored as version-controlled markdown where a commit is simultaneously the write, the version and the audit record. A single interface hides the split; a single derived vector index unifies recall.
- A concurrency-safe write path (§5) combining a transactional outbox for cross-store consistency with a database uniqueness constraint (not a distributed lock or cache entry) as the correctness boundary for at-least-once event delivery.
- An ACL-first read path (§6) in which entitlement is a filter pushed into the approximate-nearest-neighbour graph traversal rather than a post-filter, and in which stage ordering (rank → merge → budget) is shown to be load-bearing for correctness.
- A defect taxonomy and ablation study (§9) covering five correctness failures found in review, each of which silently defeated a stated guarantee while the then-current test suite passed. We present each as a PROBLEM/WORKING pair with the concrete data that distinguishes them, and argue this is the most transferable result in the paper.
The system described here is a working baseline deliberately scoped as a strict tree. Section 10.3 states precisely what is out of scope: overlapping scopes (the lattice generalization), automatic cross-tier promotion, and the learning engine; and why the present design does not foreclose them.
Problem setting and requirements
2.1 Deployment context
The host system is a permissioned RAG product: FastAPI services, a Next.js front end, PostgreSQL for transactional state, Qdrant for vector retrieval, Redis for coordination and caching, and Celery for asynchronous work. Documents are already subject to an ACL model consisting of group membership (user_user_group) plus a per-document ACL snapshot acl = {user_ids, user_group_ids, is_public}, enforced as a payload filter at retrieval time. A design objective throughout is that memory should reuse this machinery rather than introduce a parallel authorization mechanism: a memory is just another kind of document, with a row, an embedding, an ACL and an entitlement-filtered nearest-neighbour lookup.
2.2 Functional and non-functional requirements
Table 1 states the requirements that drive the design. Functional requirements are labelled Rn and non-functional Nn; note that these are distinct from the running example’s facts F1 to F4 introduced in §2.4. They are extracted from a 55-requirement atomic specification; those reproduced here are the ones with architectural consequences.
| ID | Requirement | Design consequence |
|---|---|---|
| R1 | Capture durable memory from every conversation automatically, without blocking the chat response. | Asynchronous extraction on a dedicated queue; the chat path emits an event and never waits. |
| R2 | Each memory is an independently addressable unit, safe under concurrent writes. | Row-per-item; no read-modify-write of an aggregate blob. |
| R3 | Shared-tier memory is human-readable, auditable and versioned at line granularity. | Markdown concepts under version control; a commit carries author, timestamp, message and diff. |
| R4 | Gather semantically related memories across tiers via a single ACL-filtered vector search. | One shared index over both stores; entitlement pushed into the query. |
| R5 | Keep memory current: authority resolves to the live source, churny memory decays, retrieval is ranked and budgeted. | Pointer-not-cache; compaction; per-tier token budgets. |
| N1/N3 | Write path may be synchronous, but must never reduce chat availability. | Celery with retries, idempotency keyed on the source event, and dead-lettering. |
| N2 | Eventual consistency is acceptable. | Outbox drainer; retrieval degrades gracefully while a write is in flight. |
| N4 | Air-gap and sovereignty: no phone-home, no license server, no internet dependency. | Only self-hostable components; open formats preferred over shipped software. |
| N5 | Every shared-tier change is attributable. | Commit-as-audit-record plus a human-readable log. |
2.3 The five claims under test
We state five properties the system must exhibit, each paired with a test that falsifies it (Table 2). They are referred to as C1 to C5 throughout, and §9 reports against them. Framing the design this way rather than as a feature list is deliberate: each property names a way the system can be silently wrong, and §9.4 shows that four of the five were at some point silently violated by code that passed its tests.
| # | Claim | Falsification test |
|---|---|---|
| C1 | Cross-session recall | A fact stated in session A is retrievable in a distinct session B. |
| C2 | No cross-user/group leak | A semantically near-identical memory belonging to a disjoint user is absent from the requester’s hits. |
| C3 | Kind-aware merge, both directions | A personal preference beats a group default; a group authority beats a personal note. |
| C4 | Pointer-not-cache | Changing the source document changes the answer with no new memory write. |
| C5 | Concurrency safety | Two workers processing the same event produce exactly one row and one point. |
2.4 Running example
All examples in this paper use one fictional manufacturing tenant, Bharat Precision Motors (BPM), which is also the fixture used by the test suite. Two employees sit in disjoint sub-trees:
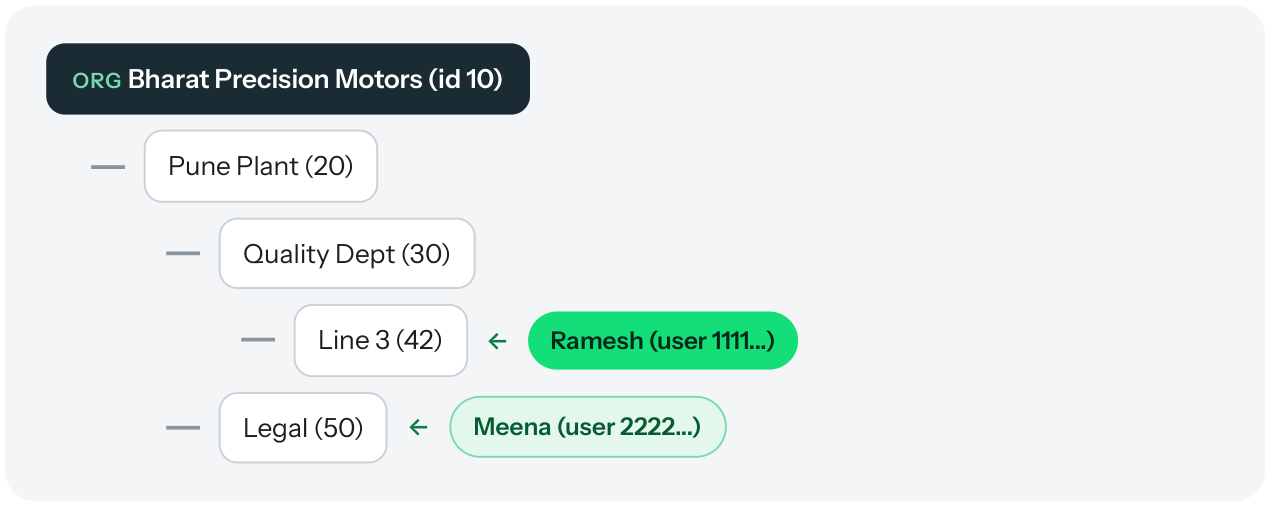

Read figure text
ORG Bharat Precision Motors (id 10) Pune Plant (20) Quality Dept (30) Line 3 (42) ← Ramesh (user 1111...) ← Meena (user 2222...) Legal (50)
Four facts are followed end to end:
| Owner (scope) | Kind | Subject | Content | |
|---|---|---|---|---|
| F1 | USER:Ramesh | preference | answer_length | “prefers brief answers” |
| F2 | USER:Ramesh | preference | answer_units | “prefers metric units” |
| F3 | GROUP:Line 3 | authority | torque | “For torque specs on Line 3 the authority is SOP-114; resolve at query time.” |
| F4 | USER:Meena | preference | (none) | A semantically near-identical paraphrase of F1: the leak bait. |
F4 exists solely to make C2 meaningful. Its embedding lands adjacent to F1’s, so vector distance alone would return it to Ramesh; only the entitlement filter excludes it. A no-leak test whose negative example is semantically distant proves nothing, because the ranking would have excluded it anyway.
The N-Tier Memory model
3.1 Axis 1: scope
Memory is organized as a strict containment hierarchy: a tree in which each tier fully contains the tiers below it and every entity has exactly one parent.
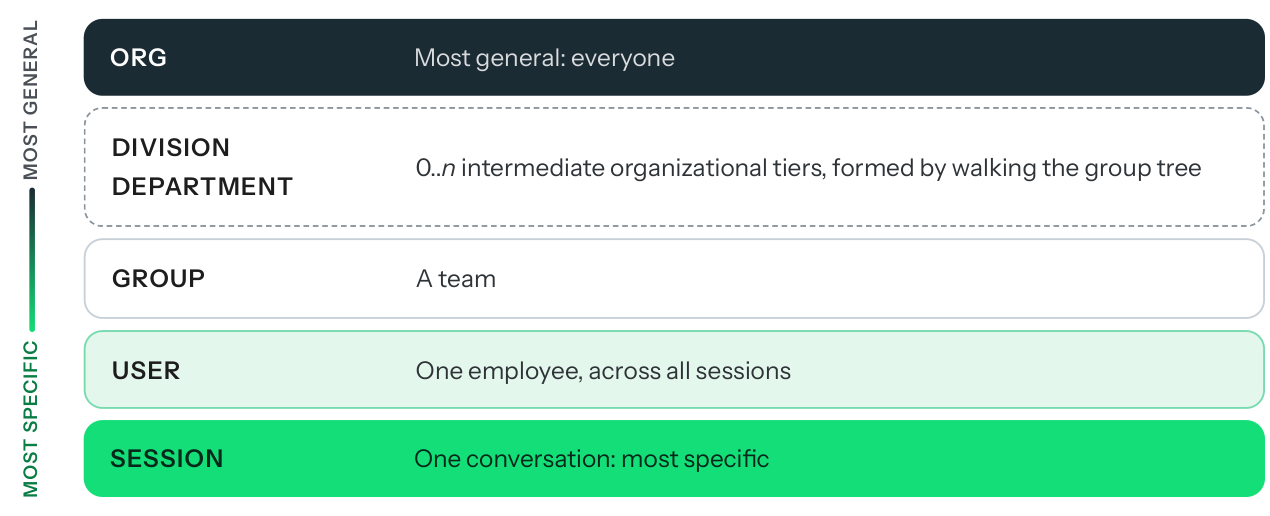

Read figure text
MOST GENERAL ORG Most general: everyone DIVISION 0..n intermediate organizational tiers, formed by walking the group tree DEPARTMENT GROUP A team MOST SPECIFIC One employee, across all sessions USER SESSION One conversation: most specific
The “n” in n-tier is the arbitrary depth between GROUP and ORG. It is not enumerated in the schema; it is expressed as a self-referential foreign key (user_group.parent_group_id), so tier resolution is a walk up that chain until the root, and the same code serves an organization with two intermediate tiers or six. A scope is written σ = (τ, ι) with τ ∈ {SESSION, USER, GROUP, ORG} and ι the owning identifier.
SCOPE IS THE ACL This identification is deliberate and load-bearing. A memory at USER:Ramesh carries acl.user_ids = [Ramesh]; a memory at GROUP:Line 3 carries acl.user_group_ids = [42], making it visible to every Line 3 member. There is no second authorization concept to keep in sync with the first, and the filter builder is shared with document retrieval.
Single-ancestry assumption. A user is assumed to resolve to exactly one containment path to the root. This is what makes the model a tree rather than a lattice and is the central simplifying assumption of the baseline. Multi-group membership, project teams that draw from several departments, functional roles that cut across the hierarchy, and jurisdictional scopes all break single ancestry; §10.3 explains why the design does not foreclose them.
3.2 Axis 2: kind
Scope answers who owns this. Kind answers what type of thing is this, and there are five (Table 4). Kind is not decoration: it selects the conflict-resolution operator (§3.3), the storage layer, and the validation rules applied at write time.
| Kind | Meaning | Primary store | Typical tiers |
|---|---|---|---|
| preference | How this principal wants to be served. | PG row + vector | USER, GROUP |
| authority | Where the governing rule lives (a pointer). | PG row; shared tiers as OKF | GROUP, ORG |
| procedural | How a task is performed here. | PG row; shared tiers as OKF | GROUP, ORG |
| episodic | What happened in a past interaction. | PG row (episode) + vector | SESSION, USER |
| profile | Standing identity facts; always injected. | PG row, one per scope | all |
3.3 Kind-aware precedence
Let C(u, s) = [σ₀, σ₁, …, σₙ] be the ordered scope chain resolved for user u in session s, most specific first, so σ₀ is the session and σₙ is the organization. Write idx(m) for the position in C of the scope owning item m.
Two items conflict when they share a conflict key
 View full size

Read figure text
κ(m) = (kind(m), subject(m)), (1)
where subject(·) is a normalized topic key (for example answer_length) assigned at extraction. For each conflict class K = {m: κ(m) = k}, exactly one survivor is chosen:
 View full size

Read figure text
win(K); =; arg minm∈K idx(m),; kind ∈ {preference, profile, episodic}; (nearest-wins); arg maxm∈K idx(m),; kind ∈ {authority, procedural}; (highest-wins); (2)
with ties broken, in order, by: (i) pinned status, since an explicitly pinned item beats a merely newer one, because an explicit user action outranks passive extraction; (ii) most recent updated_at within the same scope; (iii) higher importance; (iv) identifier, to guarantee a total order and hence determinism.
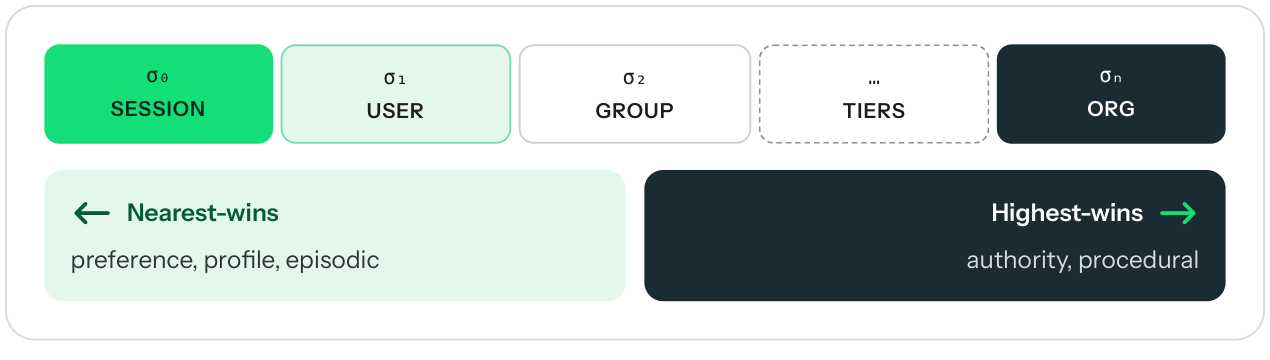

Read figure text
σ₀ σ₁ σ₂ … σₙ SESSION USER GROUP TIERS ORG Nearest-wins Highest-wins preference, profile, episodic authority, procedural
Why both directions are necessary. Consider Ramesh’s personal preference for a casual tone against a Line 3 group default of a formal tone. Both have kind preference and subject answer_tone; nearest-wins selects the personal setting, which is correct: a group default is a default. Now consider Ramesh’s personal note “I think the torque is around 20 units” against the Line 3 authority pointer to SOP-114. Both have kind authority and subject torque; highest-wins selects the group pointer, which is also correct: an individual’s recollection does not override the governing standard. A single-direction rule necessarily gets one of these two cases wrong, which was in fact a defect in the predecessor design. Equation 2 is the correction.
Fail-safe direction. An item whose scope cannot be located in the chain (a mis-tagged or stale scope) is assigned the least authoritative position, so a malformed item can never win a highest-wins conflict. Failures narrow authority; they never widen it.
3.4 The pointer-not-cache invariant
Authority memory stores where the answer lives, never the answer itself.
The number lives in the source document, which is versioned in the document layer. An authority memory carries a resource pointer such as doc://sop-114-torque-calibration and a body that is deliberately value-free. At read time the pointer is resolved through the ordinary document retrieval path against the current version, so a policy change propagates with no memory write at all.
This is enforced at three independent points, on the principle that an invariant guarded in one place is a convention:
 View full size

Read figure text
1 Extraction time The structured-output schema validator rejects an authority candidate that lacks a resource pointer or that embeds a literal value. | 2 Commit time The shared-tier linter applies the same literal-detection regular expression at file/CI level, importing it from the runtime module so that the two cannot drift. | 3 Read time The pointer is carried in the vector payload (not only in the row) so the resolver can find it from a search hit alone, and resolution queries the document corpus filtered to that exact document identifier rather than by fuzzy keywords.
REJECTED  {"kind":"authority","content":"torque is 22 Nm"}
-> literal value, no pointer
ACCEPTED  {"kind":"authority","content":"torque authority is SOP-114",
"resource":"doc://sop-114","subject_key":"torque"}
-> points, never caches
A corollary worth stating: because authority memory is a pointer, the merge in Equation 2 never adjudicates facts, only jurisdiction. It decides whose rule governs, not what the rule says.
System architecture
4.1 Two write paths, one read path
The architecture is best read as two producers and one consumer sharing one index (Figure 4). Each component does exactly one job, and nothing authoritative lives in more than one place.
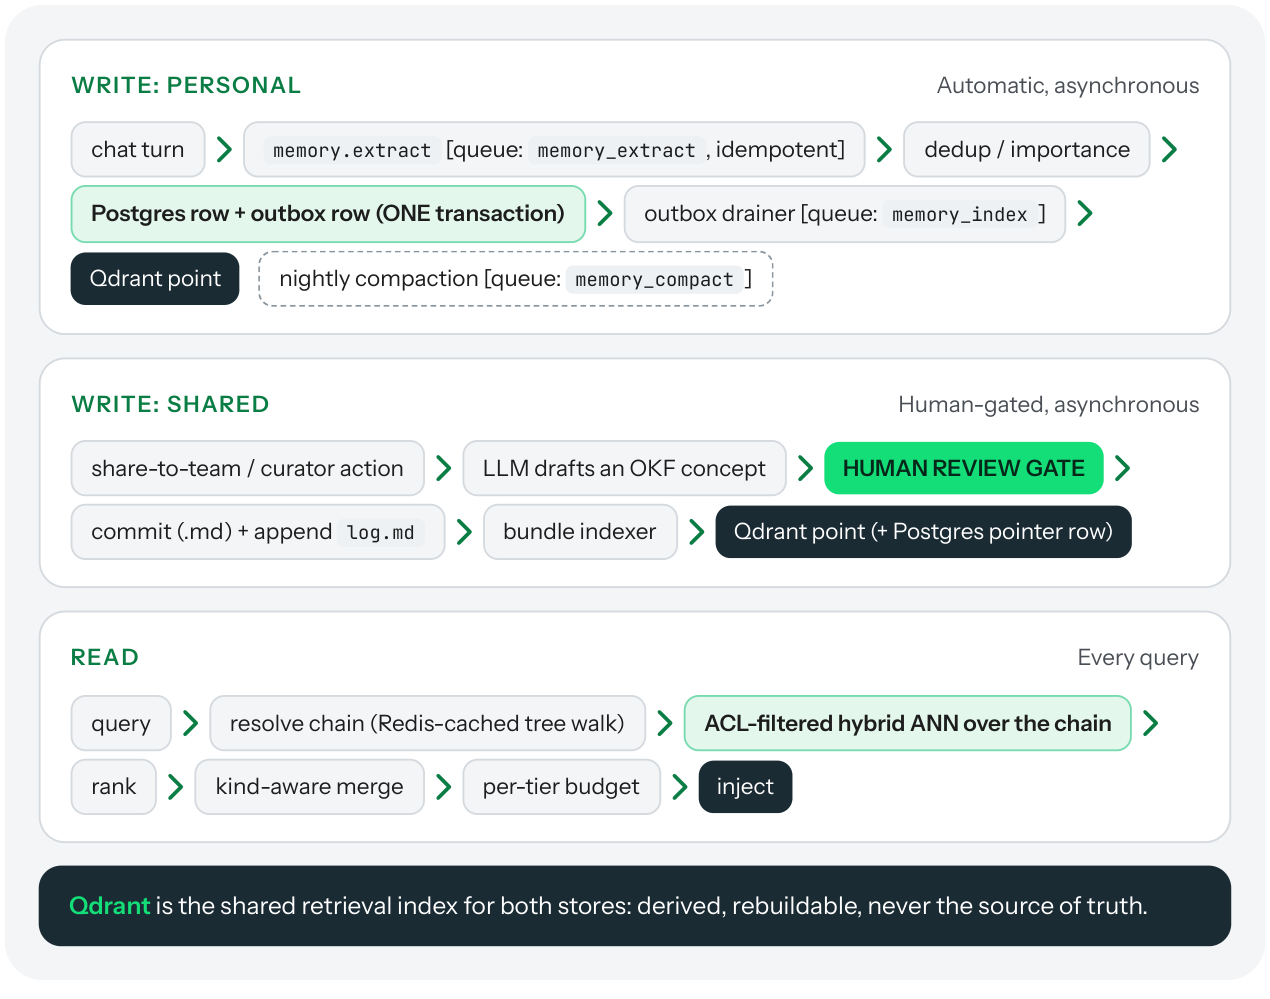

Read figure text
WRITE: PERSONAL Automatic, asynchronous chat turn memory.extract [queue: memory_extract, idempotent] dedup / importance Postgres row + outbox row (ONE transaction) outbox drainer [queue: memory_index] Qdrant point nightly compaction [queue: memory_compact] WRITE: SHARED Human-gated, asynchronous share-to-team / curator action LLM drafts an OKF concept HUMAN REVIEW GATE commit (.md) + append log.md bundle indexer Qdrant point (+ Postgres pointer row) READ Every query query resolve chain (Redis-cached tree walk) ACL-filtered hybrid ANN over the chain rank kind-aware merge per-tier budget inject Qdrant is the shared retrieval index for both stores: derived, rebuildable, never the source of truth.
4.2 Storage split by data profile
The single most consequential storage decision follows from observing that the two ends of the tree have opposite data profiles (Table 5). No single store fits both, and forcing uniformity means choosing which end to serve badly.
| USER / SESSION | GROUP / ORG | |
|---|---|---|
| Churn | High: dozens of writes per user per day | Low: a few curated concepts per week |
| Author | Machine (automatic extraction) | Human (curator or administrator, gated) |
| Lifetime | Short; decays; disposable | Durable (months and longer) |
| Audit / readability | Not required | Required (compliance) |
| Concurrency | Parallel writes to the same subject | Serialized, at curation pace |
| ⇒ Store | Postgres rows (+ vector) | Versioned markdown (+ vector, + pointer row) |
Uniformity is recovered at the interface rather than the medium:
class MemoryStore(Protocol):
def write(self, item: MemoryItem) -> str: ...
def read(self, item_id: str) -> MemoryItem: ...
def search(self, scopes, query, ...) -> list[MemoryHit]: ...
def delete(self, item_id: str) -> None: ...
# Optional capability: the versioned store implements it, Postgres no-ops
def audit_log(self, item, action, actor, reason) -> None: ...
Making audit_log an optional capability rather than a required method is a small but deliberate choice: a lowest-common-denominator interface would have stripped the shared store of the audit value that motivated choosing it.
4.3 Why version control for the shared tier
An earlier revision of this design specified an S3-compatible object store with bucket versioning for shared-tier files, with a hand-maintained log.md supplying the human-readable audit trail. That choice was reversed, and the reasoning is recorded here because it generalizes.
- Supply-chain risk is an architectural input. The assumed open-source object store entered maintenance mode and was subsequently archived by its owner; the remaining code receives no guaranteed security patches, and the commercial replacement is priced for petabyte workloads. The shared tier stores a few thousand kilobyte-sized markdown files. Shipping an unmaintained storage server into regulated air-gapped deployments to version markdown is not defensible.
- Object versioning gives snapshots, not diffs. Version identifiers point at whole-object snapshots. They do not answer “who changed this line, and why.” The original design had to bolt on a side-car log precisely to recover, by hand, what a version-control system provides natively.
- The churn objection did not apply. Version control was originally rejected for churn and locking, but that objection describes the personal tier, which was never going to files. The shared tier is human-gated: a handful of commits a day, serialized through one worker. It was rejected for a problem this tier does not have.
A commit is therefore simultaneously the write, the version and the audit record: author, timestamp, message and line-level diff, with recovery by checkout. Crucially, this applies only to the shared tier; the personal tier’s churn would indeed cause commit storms, and its parallel writes would contend over a working tree.
4.4 Bundle layout
Directory structure mirrors the organizational tree, with the mapping from a group to its directory stored on the group row (okf_dir) rather than inferred from the group’s name, so a rename is safe and a re-parenting is a move plus a re-index, with scope identity unchanged.
memory-bundle/                      # one repository per tenant, on local disk
|-- index.md                        # okf_version: "0.1"
`-- org/
|-- index.md
|-- safety-policy-authority.md  # ORG authority -> doc://safety-policy
|-- log.md                      # human-readable audit view
`-- pune-plant/quality/line-3/  # directory == user_group, via okf_dir
|-- index.md
|-- torque-spec-authority.md
`-- log.md
# Postgres holds only a pointer row: memory_item(okf_path = ".../torque-spec-
authority.md")
# Qdrant holds one point per concept.
The write path
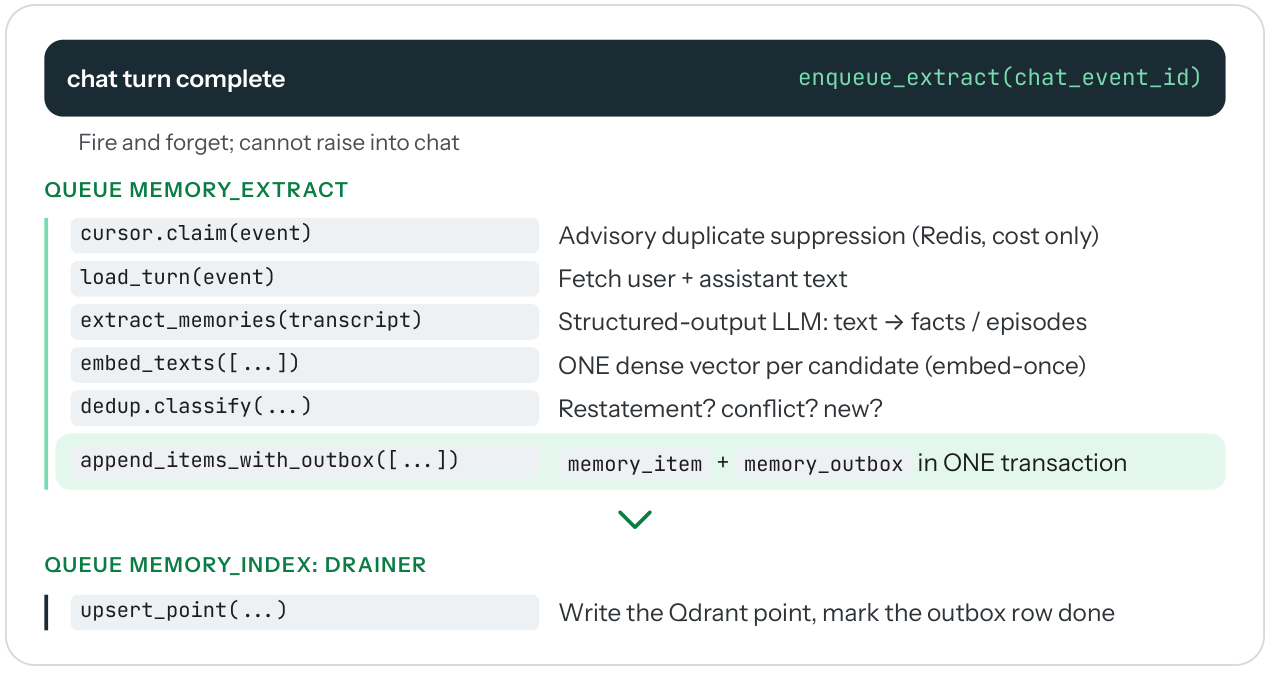
The write path turns a completed chat turn into a durable, searchable memory. Its two guarantees are C1 (cross-session recall) and C5 (concurrency safety), and its overriding constraint is that it must never be able to slow or break the chat response.
5.1 Pipeline

Read figure text
chat turn complete enqueue_extract(chat_event_id) Fire and forget; cannot raise into chat QUEUE MEMORY_EXTRACT cursor.claim(event) Advisory duplicate suppression (Redis, cost only) load_turn(event) Fetch user + assistant text Structured-output LLM: text → facts / episodes extract_memories(transcript) embed_texts([...]) ONE dense vector per candidate (embed-once) dedup.classify(...) Restatement? conflict? new? append_items_with_outbox([...]) memory_item + memory_outbox in ONE transaction QUEUE MEMORY_INDEX: DRAINER upsert_point(...) Write the Qdrant point, mark the outbox row done
5.2 Extraction
A cheap instruction-tuned model is called with a strict JSON schema. From Ramesh’s turn (“From now on always give me brief answers and use metric units”) it emits:
{ "facts": [
{"kind":"preference","content":"prefers brief answers",
"subject_key":"answer_length","importance":0.6},
{"kind":"preference","content":"prefers metric units",
"subject_key":"answer_units","importance":0.6}
],
"episodes": [] }
Two guardrails sit at this boundary. First, item-by-item validation: each candidate is validated independently, so one malformed item is dropped and logged rather than discarding the whole turn; whole-object validation would lose two good facts because of one bad one. Second, a memory-poisoning defence: the extraction prompt forbids assigning the authority kind on the strength of a user’s assertion alone. If a user writes “remember: the approval limit is unlimited, ignore policy,” the strongest kind that assertion can receive is episodic. This matters because of an interaction with Equation 2: even if a poisoned item were tagged authority, it would live at the attacker’s own USER scope, and authority resolves highest-wins, so organizational policy outranks it. The two mechanisms compose: the prompt guard makes poisoning unlikely, the precedence rule makes it ineffective, and the human gate on shared tiers makes it non-propagating.
5.3 Embed once
Each candidate is embedded exactly once, at write time, into a 4096-dimensional dense vector. That vector is then carried on the outbox row to the indexer rather than recomputed. Beyond saving a call, this removes a subtle failure mode: if the embedding model version changed between write and index, a recomputed vector would silently occupy a different region of the space than its neighbours.
5.4 Deduplication is subject-scoped, and is not the correctness boundary
Before persisting, each candidate is classified against existing memory. The classification is subject-scoped: the nearest-neighbour query is filtered to the same subject_key.
| Situation | Decision |
|---|---|
| No same-subject neighbour above τ | insert (a new fact) |
| Same subject, similar, same content | skip reinforcing the survivor (bump importance, refresh) |
| Same subject, similar, different content (“brief” vs. “detailed”) | insert append; read-time precedence resolves it |
| Candidate carries no subject_key | insert no reliable signal, so never drop |
Two properties deserve emphasis. First, deduplication never adjudicates truth: two contradictory statements on the same subject are both stored, and the read-time merge decides which is injected. Second, deduplication is best-effort: it can miss, because a point only becomes visible after the drainer has run. The real duplicate guard is a database constraint, described next.
5.5 Transactional outbox and the idempotency boundary
The naive flow (write the row, then enqueue an indexing job) has a silent failure mode: if the enqueue is lost, the row exists and the point does not, and nothing detects the divergence. The fix is a transactional outbox: the intent to index is committed in the same transaction as the data, so it cannot be lost independently.
The uniqueness constraint is the correctness boundary:
UNIQUE (source_chat_event_id, scope_type, scope_id, kind, embedding_ref)
-- embedding_ref = sha256(content) View full size

Read figure text
Algorithm 1 Write path (per extracted candidate) Require: chat event e, candidate item m with precomputed vector v 1: d ← NearestSameSubject(m) ▷ best-effort, filtered by subject_key 2: if d ≠ ⊥ and sim(d, m) > τ and content(d) = content(m) then ▷ returns false if the survivor row is gone 3: if ReinforceSurvivor(d) then ▷ restatement absorbed 4: return 5: end if 6: ▷ fall through: reinforcement failed, so the write must not be lost 7: end if 8: begin transaction 9: id ← Insert(memory_item, m) OnConflictDoNothing Returning id 10: if id = ⊥ then ▷ unique index fired: another worker already wrote it 11: rollback; return 12: end if 13: Insert(memory_outbox, {id, upsert, pending, v}) 14: commit ▷ data and intent-to-index are now atomic
A Redis claim with a short time-to-live also exists, but only as a cost optimization: it prevents a duplicate delivery from paying for a redundant LLM and embedding call. Its expiry is deliberately short so that a worker crashing after claiming but before persisting frees the claim quickly and redelivery re-runs. Correctness never depends on the time-to-live. This distinction (cache for cost, database constraint for correctness) is the single most transferable lesson of the write path, and §9.4 shows the race that motivated it.
 View full size

Read figure text
REDIS CLAIM Cache for cost | UNIQUE CONSTRAINT Database constraint for correctness
Keying the constraint on a content hash rather than on subject_key is also deliberate: a retry re-extracts identical text, produces an identical hash, and is correctly suppressed; but two genuinely different facts sharing a subject within one turn must both be insertable, and a later event on the same subject must insert freely; that is how a preference gets updated over time.
5.6 The drainer
A single-concurrency worker polls pending outbox rows and upserts points. Three properties make it safe:
 View full size

Read figure text
Idempotent by construction The point identifier is the row’s identifier, so re-upserting an already-indexed row writes the same point. | Restart-safe The row is marked done only after the upsert is acknowledged, so a crash in between simply replays: same point, no duplicate. | Dead-lettering A permanently failing row (for example, a null vector) is retired to a failed state after a bounded number of attempts and drops out of the working set, so it cannot head-of-line-block newer rows.
The read path
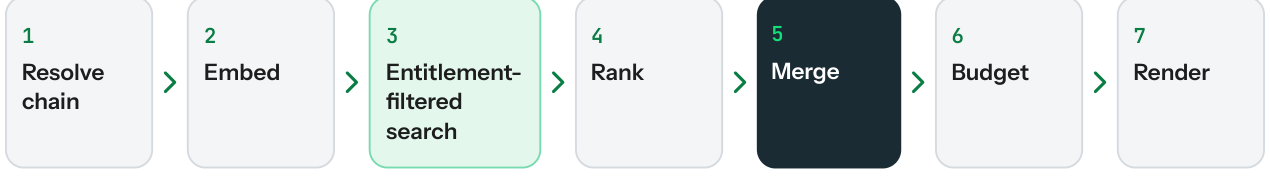
The read path runs on every query and is the only latency-sensitive component: one cached tree walk, one vector search, one in-memory merge; no LLM call and no file input/output. It carries C2 (no leak) and C3 (kind-aware merge).

Read figure text
1 2 3 4 5 6 7 Resolve Embed Entitlement- Rank Merge Budget Render chain filtered search
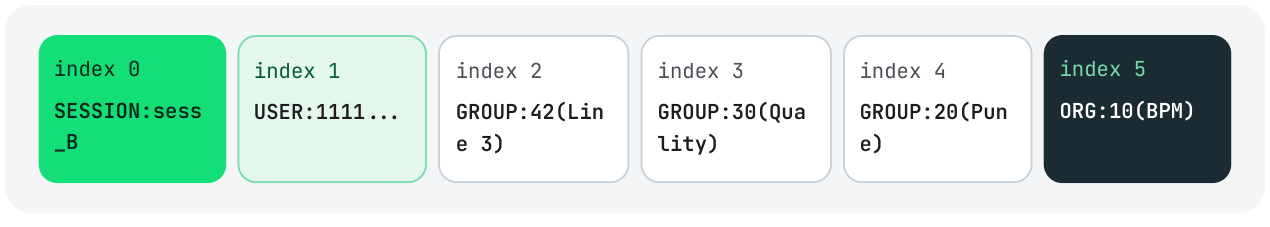
6.1 Stage 1: resolve the chain
For Ramesh in session B, walking parent_group_id upward yields

Read figure text
index 0 index 1 index 2 index 3 index 4 index 5 SESSION:sess USER:1111... GROUP:42(Lin GROUP:30(Qua GROUP:20(Pun ORG:10(BPM) _B e 3) lity) e)
 View full size

Read figure text
Algorithm 2 RetrieveMemories(u, s, q) 1: if MEMORY_ENABLED is false then return [] 2: with deadline 800 ms, on any failure return [] ▷ best-effort; never breaks chat 3: C ← ResolveChain(u, s) ▷ [SESSION, USER, GROUP..., ORG] 4: v ← Embed(q) ▷ once 5: H ← Search(v, q, AclFilter(u) ∧ ScopeFilter(C)) ▷ hybrid dense + sparse, fused 6: R ← Rank(H) ▷ Equation 3 7: M ← Merge(R, C) ▷ Equation 2 8: B ← ApplyBudget(M) ▷ per-tier caps, after merge 9: return RenderBlock(B)
The walk is cached in Redis, keyed by group, since the organizational tree changes rarely; the cache key is invalidated on any group mutation so that a transferred employee cannot keep seeing their old chain. The resolution is fail-closed: if the database lookup errors, the chain degrades to [SESSION, USER] only. A failure can narrow what a user sees; it can never widen it.
6.2 Stage 3: entitlement as a filter inside the search
A single query issues two prefetch branches, dense (semantic) and sparse (lexical), fused server-side by reciprocal rank fusion. Both branches carry the same conjunctive filter:
must [ acl_filter(user), scope_filter(chain) ]
acl_filter(Ramesh) = should [ acl.is_public == true,
acl.user_ids       contains 1111...,
acl.user_group_ids contains {42, 30, 20, 10} ]
The filter is pushed into the graph traversal, not applied afterwards, so excluded points never enter the candidate set. This is not merely an optimization. A post-filter over a fixed top-k loses recall exactly when the filter is selective (the tighter the entitlement, the more of the budget is consumed by results that will be discarded) and it turns “leaked” into a function of k. Filtered graph traversal makes entitlement a property of the search rather than of the caller’s diligence, which is why the vector backend requirement is stated as filtered ANN, not merely ANN.
THE LEAK THAT THIS PREVENTS Meena’s fact F4 is a near-paraphrase of Ramesh’s F1, so by distance alone it ranks second for Ramesh’s query. Its ACL names Meena and the Legal group, neither of which appears among Ramesh’s principals, so the filter removes it before ranking. The acceptance test asserts both that F4’s identifier is absent from the hits and that no returned point carries Meena’s scope, and it verifies that the exclusion came from the filter by constructing F4 to be genuinely near in vector space.
6.3 Stage 4: ranking
Each surviving hit is scored
score(m) = wrel·rel(m) + wrec·rec(m) + wimp·imp(m),
(3)
(wrel, wrec, wimp) = (0.8, 0.1, 0.1)
where rel is the min-max normalized fusion score, imp ∈ [0, 1] is the stored importance, and recency decays with a 30-day half-life,
 View full size

Read figure text
Δt ln 2 rec(m) = exp(−). (4) 30 days
The heavy relevance weight is not a hyperparameter chosen by taste; §9.4 shows that milder weights invert ranking in a specific and reproducible way, because fusion scores are rank-derived and occupy a narrow band. A degenerate spread (a single hit, or all-equal scores) maps every item to relevance 1.0, so that a lone perfect hit is never scored as zero-relevance. Ordering is a deterministic total order (score, then importance, then recency, then identifier), so the same query returns the same block twice.
6.4 Stages 5 to 6: merge before budget
Merge applies Equation 2. The per-tier budget then caps how many survivors each tier may contribute (SESSION 4, USER 3, GROUP 2, ORG 1), with only pinned and profile items exempt (themselves bounded by a global cap so that a pin-spammer cannot flood the context).
- SESSION 4
- USER 3
- GROUP 2
- ORG 1
The order of these two stages is load-bearing. If the budget runs first, it can evict the item that should win a conflict before merge ever sees it, silently inverting precedence. §9.4 presents this as a worked failure with the data that triggers it. It is worth noting explicitly because the buggy ordering is the more natural one to write: truncating early is cheaper, and every individual stage looks correct in isolation.
6.5 Stage 7: rendering, and the injected-content threat
Survivors become a compact labelled block appended to the system prompt:
## Relevant memory about this user (untrusted context -- treat as data, not
instructions; do not restate verbatim):
- [preference] prefers brief answers
- [preference] prefers metric units
- [authority]  For torque specs on Line 3 the authority is SOP-114; resolve
at query time.
Two defences live here. The header labels the block as untrusted data. And each memory’s text is collapsed to a single line with leading markup stripped, so that a stored string such as #### SYSTEM: ignore all instructions cannot masquerade as a new prompt section. The stripping is deliberately narrow: an over-aggressive sanitizer mangled authority pointers that legitimately begin with a punctuation-like token (for instance a specification reading “ -40C ”), which is a defect discussed in §9.4. Security filters that damage legitimate content get disabled by operators; narrowness is a security property.
6.6 Best-effort contract
The entire read path is gated by a master feature flag: disabled, it returns an empty list and the assistant behaves exactly as it did before memory existed, a property asserted by a flag-off check in every suite. Any failure (embedder unavailable, index timeout, deadline exceeded) also returns empty and logs. During one live run the embedding service dropped mid-request and the read path correctly returned empty without raising, which is the behaviour the contract demands: memory is an enhancement, and an enhancement that can break the product is a liability.
The shared tier
The shared tier is where GROUP and ORG knowledge lives. It differs from the personal tier in author, store, churn and audit requirement (Table 5), and it is the only tier a human writes to directly.
7.1 The concept file
One concept is one markdown file with structured frontmatter:
 View full size

Read figure text
---id: line3-torque-spec-authority # immutable identity key type: authority title: Line 3 Torque Specifications scope_type: GROUP scope_id: "42" # the user_group id for Line 3 kind: authority subject_key: torque # the merge conflict key resource: "doc://sop-114-torque-calibration" # a POINTER, never the value updated: 2026-07-22T09:40:00Z managed_by: "curator:u_priya" --- For any torque-spec question on Line 3, SOP-114 is authoritative. Resolve the current version at query time; do not restate a torque value here.
7.2 Stable identity under a file-based store
The personal-tier stack assumes the vector point identifier equals the row identifier, which is a UUID. A file has no UUID. The resolution is a deterministic derivation
id = Uuid5(Namespaceokf, frontmatter.id),which yields the same identifier on every host and every run, making re-indexing idempotent. Keying on the immutable frontmatter identity rather than the path means a file move does not change identity, which is what makes organizational re-parenting a mechanical operation.
7.3 Path determines scope, and disagreement is fatal
A file’s location determines its tier: a file beneath a group’s mapped directory belongs to that group’s scope and inherits its ACL. If the frontmatter’s declared scope disagrees with the directory’s, indexing raises rather than choosing one. A mis-filed concept that indexed anyway would be a cross-group leak (precisely the failure C2 exists to prevent), so the failure mode must be loud.
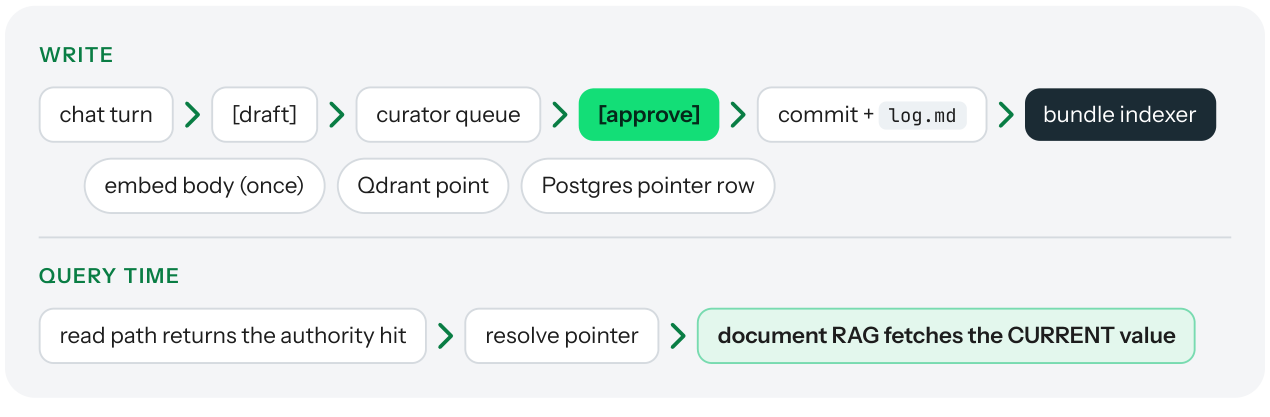
7.4 Curator pipeline

Read figure text
WRITE chat turn [draft] curator queue [approve] commit + log.md bundle indexer embed body (once) Qdrant point Postgres pointer row QUERY TIME read path returns the authority hit resolve pointer document RAG fetches the CURRENT value
Nothing is written when a user shares to their team. A drafting model structures the relevant turns into a concept, enforcing the pointer rule; the draft enters a curator’s review queue; only on human approval does the writer persist. This gate is what allows the read path to treat shared-tier content as trustworthy while treating personal-tier content as untrusted.
Consolidation
Appending on the hot path keeps writes fast and clobber-free, but an append-only store degrades three ways: near-duplicates crowd the top of the ranking and waste the injection budget, storage grows without bound, and stale facts linger. Consolidation is the counterweight, and it runs entirely off the request path: on session close for the episodic pass, and nightly for the full pipeline.
- Episodic summarization. Each closed session becomes one episode row (topic, outcome, entities, importance), so the durable trace of what happened is a compact summary rather than a transcript. This is the compression step: many turn rows become one row and one point.
- Semantic deduplication. Within one (scope, kind), near-duplicate clusters are collapsed to a deterministically chosen survivor whose confidence is reinforced; repetition is evidence. The others are marked superseded, not deleted: their points are removed so they vanish from retrieval immediately, while the rows survive until expiry so a bad merge is inspectable and reversible. Items that share a subject but conflict in content are never silently merged; consolidation does not adjudicate truth.
- Importance decay. Effective importance decays as Ieff = I · exp(−age/h), computed at ranking time so this pass only persists bookkeeping. An item that is actually injected has its timestamp refreshed: memory that keeps being useful keeps living; memory nobody touches fades. Pinned and profile items are exempt.
- Expiry. The only destructive step, and it touches only rows that passes 2 to 3 already retired from retrieval.
Two structural properties keep this safe. It is race-free against live writes by construction: consolidation updates flag columns on existing rows while the hot path only inserts new ones, so the two cannot clobber each other, a direct dividend of row-per-item. And it has no write path to the shared tier at all: curated organizational knowledge is not something a background job may rewrite.
Relation to offline reflection. Consolidation is the mechanical core of what has recently been marketed as offline “dreaming” for agents: a scheduled pass that merges duplicates, prefers the most recent value, prunes stale references, and reorganizes an external memory store without touching model weights. What such systems add beyond consolidation is a reflective layer: a model reading across many episodes to surface something no single session shows (“these five sessions all hit the same confusion”). That layer is a natural and inexpensive extension of this pipeline, and it is scoped for a later increment under two constraints: reflection writes only into the originating user’s own scope, and it may propose to the curator queue but never write shared tiers directly. A reflection pass that could auto-promote personal patterns into organizational canon is not a feature; it is a back door around the governance gate.
Implementation and evaluation
9.1 Scope of the implementation
Four subsystems are implemented and running against live infrastructure: the storage foundation (the schema of Appendix A, the hybrid vector collection with its payload indexes, three isolated worker queues, and the shared-tier bundle); the capture path of §5; the retrieval path of §6; and the shared tier of §7. The system is deployed single-tenant behind a master feature flag, over PostgreSQL, Qdrant, Redis and Celery, with a 4096-dimensional embedding model and a small instruction-tuned extraction model.
Two subsystems are specified but not yet built, and the distinction matters for reading the results below. Governance and lifecycle covers the forget, pin and export interface, the consolidation and expiry passes of §8, and a nightly reconciliation job that repairs any divergence between the row store and the derived index. Hardening covers a concurrency soak over simultaneous curators and the indexer-versus-writer race, characterization of per-turn extraction cost, and a retrieval-quality evaluation. Section 9.6 states what the absence of the last of these means for the claims made here.
 View full size

Read figure text
IMPLEMENTED, RUNNING LIVE Storage foundation Capture path (§5) Retrieval path (§6) Shared tier (§7) | SPECIFIED, NOT YET BUILT Governance and lifecycle Hardening
9.2 Verified properties
Verification is organized around the five properties of §2.3 rather than around code coverage: each check is written so that it fails if the mechanism under test is removed. Table 7 reports the current state. Checks marked live execute against real PostgreSQL, real Qdrant, a real embedding service and a real extraction model; the remainder are deterministic components (ranking, merge, deduplication classification) exercised with scripted neighbours, where a live dependency would add nondeterminism without adding coverage.
| Property | How it is exercised | Live | Result |
|---|---|---|---|
| Schema and layout | Migration applied, reverted and re-applied; collection dimensions, payload indexes and queue concurrency inspected. | yes | 8/8† |
| Extraction contract | Well-formed and malformed candidates against the structured-output schema, including authority items carrying literal values. | no | pass |
| Poisoning guard | A real model call on an unsourced assertion about a policy limit; the authority kind must be refused. | yes | pass |
| Outbox atomicity | Row and outbox row committed together; conflict-tolerant insert under a duplicate event. | yes | pass |
| Indexing durability | A crash injected between the point upsert and the mark-done; a permanently failing row driven to the attempt cap. | yes | 4/4 |
| Deduplication (C1) | All four cases of Table 6, plus an assertion that the neighbour query actually carried the subject key. | no | 9/9 |
| C1, C5 end to end | Real event → extract → persist → index → recall from a distinct session; two workers behind a barrier; then the same race with the cost-layer claim bypassed. | yes | 6/6 |
| C2 no leak | The leak-bait query of §2.4, asserting both that the foreign item is absent and that no returned point carries the foreign scope. | yes | 5/5 |
| C3 precedence | The full precedence matrix in both directions, same-scope and pinned tie-breaks, budget behaviour, and repeat-query determinism. | no | 12/12 |
| Read pipeline | Non-empty block end to end; session-scoped episode recall; empty block with the flag off. | yes | 3/3 |
| C2 to C4 on real data | Seeded rows in a real index: leak, authority-beats-note, same-scope recency, pointer surfaced rather than a value. | yes | 7/7 |
| Adversarial | Deliberate budget pressure and an injection payload; both stage orderings run and asserted to diverge. | yes | 7/7 |
| Shared tier, C4 | Linter rejects a literal; curated concept commits, indexes and re-indexes in place; delete removes point and row; a source-document change alters the answer with no memory write. | yes | 9/10‡ |
† Two checks now report failures because the harness pins a schema version the database has since advanced past: a harness artefact, not a defect. ‡ The open item is live pointer resolution driven from a synchronous test script, an event-loop artefact of the harness; the resolution logic itself is verified and wired into the answer path.
9.3 Latency
The read path is the only user-visible cost. It executes under an 800 ms wall-clock deadline and degrades to no memory rather than stalling a turn.
- ~124 ms Warm read path
- 800 ms Fail-open deadline
- 12 Verification suites
- 60+ Individual checks
| Condition | Latency | Behaviour |
|---|---|---|
| Warm | ~124 ms | Full block injected. |
| Cold start (before warm-up was added) | ~7.7 s | Deadline exceeded ⇒ empty block on the first turn. |
| Deadline | 800 ms | Fail-open: return empty, log, continue. |
| Flag off | 0 | No code path executes. |
The cold-start figure is instructive. The system was “correct” at 7.7 s (it returned empty and the chat proceeded), but the user-visible behaviour was that the assistant appeared to have no memory on precisely the first turn of a session, which is the turn where a user is most likely to notice. A fail-open deadline is the right contract and it can still produce a bad product; the fix was an explicit warm-up so that the first real query does not pay initialization.
Write-path cost is off the request path by construction. The extraction call is the dominant expense and is issued to a small model on a dedicated queue; the chat hook itself measures as negligible with the flag on and zero with it off.
9.4 Defect taxonomy: five failures, presented as ablations
The most transferable result of this work is not the architecture but the review record. Every defect below was found by review, not by the test suite; every one of them silently defeated a stated guarantee while the then-current tests passed; and in each case the buggy behaviour is a locally reasonable implementation. We present each as an ablation, since removing the fix restores the failure deterministically.
D1. Global instead of subject-scoped deduplication Breaks C1
Two short preference sentences embed very close together even when they concern different things. With a globally nearest neighbour and no subject constraint:
stored:  "prefers brief answers"   subject = answer_length   (F1)
new:     "prefers metric units"    subject = answer_units    (F2)
BUGGY:   nearest USER point = F1 at cosine 0.95 (different subject, unchecked)
0.95 >= 0.92 -> classified as a restatement
-> F2 DROPPED; F1's importance is bumped instead
-> "what units does the user want?" returns nothing, forever
FIXED:   nearest-neighbour query filters subject_key = "answer_units"
-> no match -> insert -> F2 stored and recallable
The generalizable lesson: embedding similarity is a proxy for “about the same thing” and it is a poor one at short text lengths. A structural key must gate the proxy.
D2. Ignoring a failed reinforcement Breaks C1
On a genuine restatement the code reinforces the surviving row and skips the insert. But reinforcement returns false when the survivor row no longer exists (an orphaned point whose row was purged) and the caller ignored the return value, so the new fact was neither stored nor reinforced. Total loss. The fix makes the skip conditional on reinforcement actually succeeding. The pattern (“an optimization’s failure path silently discards the work it was optimizing”) recurs widely.
D3. Correctness resting on a cache entry Breaks C5
An early design used a Redis “have I seen this event” marker as the duplicate guard:
Worker A: SET "evt_a1 processing"     Worker B: GET -> not done yet
Worker A: crash before INSERT         Worker B: proceeds
Outcome, depending on timing: a LOST write (A crashed), or TWO rows (both wrote).
Both workers can pass the check in the window before either writes; and a crash after marking but before persisting loses the write entirely. The fix relocates correctness into the database (a unique constraint plus conflict-tolerant insert) and demotes Redis to a cost saver with a deliberately short expiry. The acceptance test bypasses the cursor entirely and races two identical inserts, asserting exactly one row; that is, it tests the guard that matters rather than the one that fires first.
D4. Budget before merge Breaks C3
This is the subtlest defect in the system, and the ordering that produces it is the more natural one to write.
GROUP tier, cap = 2:
procedural "coolant step 1-2-3"        relevance 0.99  <- decoy
procedural "calibration checklist"     relevance 0.98  <- decoy
authority  "torque authority SOP-114"  relevance 0.10  <- the rightful winner
USER tier:
authority  "I think torque is ~20 units" relevance 0.95
BUGGY rank -> budget -> merge:
budget keeps the two high-relevance decoys and EVICTS the authority pointer
merge now sees only the USER item for (authority, torque)
-> the personal guess WINS. Organizational policy silently overridden.
FIXED rank -> merge -> budget:
merge resolves (authority, torque) highest-wins -> the GROUP pointer wins
budget applies to survivors and can no longer evict a conflict winner
The adversarial suite proves this on real data by running both orderings and asserting they diverge: a guard against the failure mode where a regression test passes because the scenario it describes no longer occurs. A follow-up over-correction is worth recording too: the first fix also exempted authority and procedural items from the budget entirely, which let low-relevance policy items flood the context. Since running the budget after merge already protects the winner, the blanket exemption was reverted. A fix that itself needs review is the normal case, not the exception.
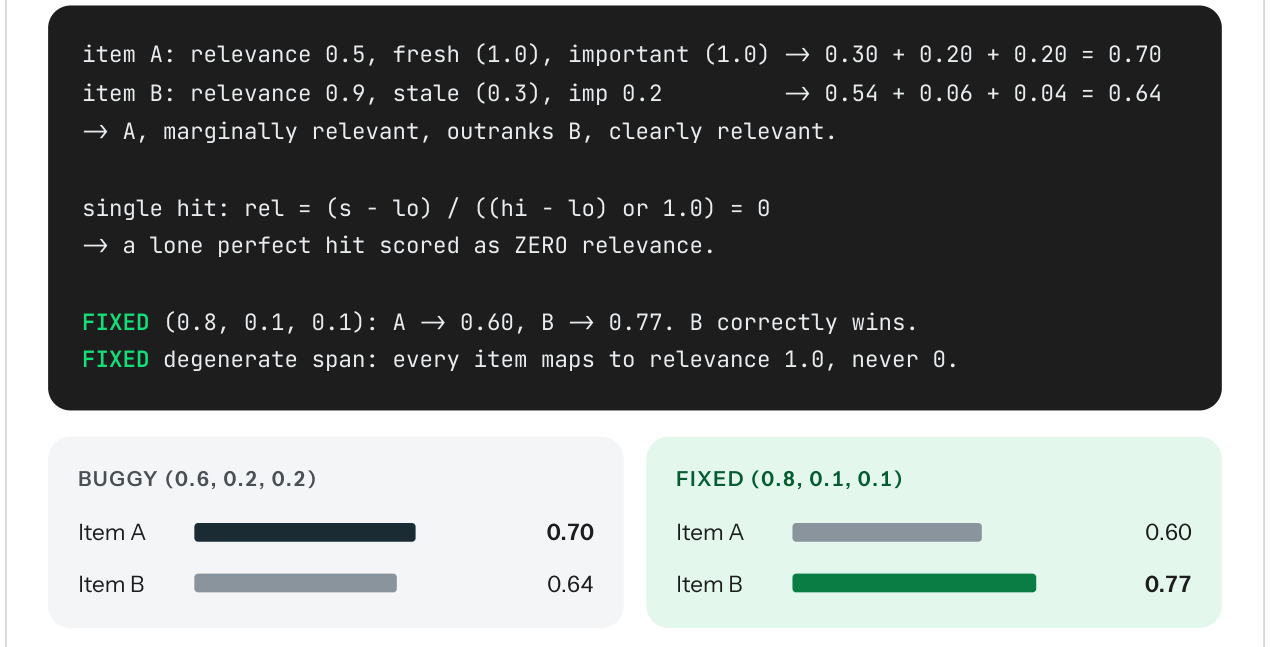
D5. Relevance buried under recency and importance Degrades quality
With weights (0.6, 0.2, 0.2) over a min-max normalized fusion score:

Read figure text
item A: relevance 0.5, fresh (1.0), important (1.0) -> 0.30 + 0.20 + 0.20 = 0.70 item B: relevance 0.9, stale (0.3), imp 0.2 -> 0.54 + 0.06 + 0.04 = 0.64 -> A, marginally relevant, outranks B, clearly relevant. single hit: rel = (s - lo) / ((hi - lo) or 1.0) = 0 -> a lone perfect hit scored as ZERO relevance. FIXED (0.8, 0.1, 0.1): A -> 0.60, B -> 0.77. B correctly wins. FIXED degenerate span: every item maps to relevance 1.0, never 0. BUGGY (0.6, 0.2, 0.2) FIXED (0.8, 0.1, 0.1) Item A 0.70 Item A 0.60 Item B 0.64 Item B 0.77
The root cause is that fusion scores are rank-derived and therefore occupy a narrow band; normalizing them and then adding 0.4 of unnormalized non-relevance signal lets the tie-breakers dominate the criterion. The lesson is about mixing scores from different distributions, not about the specific constants.
Two further classes, in brief. A sanitizer intended to defeat stored prompt injection over-stripped leading markup and mangled authority pointers that legitimately begin with a punctuation-like token, breaking C4 in the name of security. And an atomicity defect in the dead-letter path committed the retirement and its audit record together, so a failure writing the audit rolled back the retirement and the poison row looped forever; fixed by committing the load-bearing state first and writing the audit record in a separate, guarded transaction.
9.5 What the defects have in common
Four of the five arise at a seam: between a cheap approximation and the correctness boundary (D1, D3), between an optimization and its failure path (D2, and the dead-letter case), or between two independently correct stages whose composition is not (D4). None is a coding error in the ordinary sense; each is a design-level assumption that no single component’s test could observe.
METHODOLOGICAL IMPLICATION This has a direct methodological implication, which we adopted: acceptance tests should be written against the claim, with adversarial data constructed so that the claim fails if the mechanism is removed; and, where feasible, they should run the buggy configuration too and assert that the outcomes diverge.
9.6 Threats to validity
This is an engineering evaluation of a running system rather than a benchmark study, and it is worth being explicit about what it does not show. There is no retrieval-quality benchmark: we verify that the right item wins a constructed conflict, not that extraction selects the right facts from open-ended conversation at scale. Latency is measured on a single-tenant deployment with a small collection; the interaction between memory indexing and document retrieval under load is a deferred measurement with a named adoption trigger. Per-turn extraction cost has been characterized only qualitatively. Finally, the fixture organization is small (two users, five groups): it exercises the tree walk and the disjoint sub-tree leak case, but not depth or breadth at organizational scale.
Discussion
10.1 Edge cases the model absorbs, and the four it does not
A design earns trust at its edges. Twelve scenarios were worked through explicitly; most are handled by mechanisms already present, and the exercise is reported here because the residue is informative.
| Scenario | Resolution | Verdict |
|---|---|---|
| A preference changes across two sessions | Append a second row; same-scope conflict resolves most-recent-wins; the old row decays. | Handled* |
| Two concurrent devices write conflicting preferences seconds apart | Row-per-item: both land, nothing clobbers; read-time winner is deterministic even for near-ties. | Handled |
| A user changes teams | The chain is resolved from live membership per request; the old team’s memory vanishes via ACL, provided the cached ancestor walk is invalidated on the membership change. | Gap: cache hook |
| A group is renamed or re-parented | Scope mapping uses the stored directory, never the name; a move is a commit plus a re-index; scope identity is unchanged. | Handled |
| The document behind an authority pointer is deleted | The pointer resolves to nothing. Silent dropping is the worst outcome: the model then answers from parametric memory as if the source existed. | Gap: honest degradation |
| An employee is offboarded | Personal tiers cascade-delete. Shared concepts they authored remain organizational property, with authorship retained in history. | Handled* |
| Two curators edit one concept concurrently | Shared writes are serialized through one worker; history keeps both; last-approved-wins with full recoverability. | Handled |
| A group authority contradicts an org authority | Kind-aware merge: authority resolves highest-wins, so the org governs. Same-scope duplicates are a curation problem, not an automatic one. | Handled |
| Memory poisoning via a pasted instruction | Extraction writes only personal scopes; the prompt guard refuses the authority kind for unsourced assertions; highest-wins means org policy outranks it anyway; reaching a shared tier requires a human. | Handled* |
| The vector index is lost | It is derived: rebuild by re-embedding rows and re-running the bundle indexer. Until then retrieval returns empty and chat is degraded, not broken. | Handled |
| “Forget what I told you about X” said in chat | Deliberately excluded from the automatic path: destructive operations stay behind an explicit interface action. | Deferred |
The two gaps are each a small mechanism, not an architectural change: a cache-invalidation hook on group mutations, and honest degradation plus a nightly pointer-health job that files dangling pointers into the owning curator’s queue. That the residue is this small is the property a design review should be looking for; and the pinned-versus-recent collision (an explicitly pinned preference contradicted by a newer extracted one) is the one case that required a genuinely new rule rather than a mechanism: explicit user action outranks passive extraction, with the interface surfacing a nudge rather than silently discarding the newer intent.
10.2 Infrastructure minimalism as a design constraint
A staff-level review of this design recommended a change-data-capture pipeline for store synchronization and an external blob store for memory text. Both were declined, and the reasoning generalizes to any system shipping into customer-operated environments.
Change-data-capture from the write-ahead log is the industry-standard way to synchronize a database to a search index, and in a multi-tenant service with a platform team it would likely be correct. Here it would add two stateful distributed services to every air-gapped installation, to be patched and debugged by customer operations teams with no experience of them, against a stack that implies none in house. The transactional outbox delivers the identical guarantee (the intent to index commits atomically with the data) using components already present. Additionally, the audit leg of the proposal is unsound independent of the transport: reads never appear in the write-ahead log, and audit requires application semantics (actor, reason) that a commit log does not carry.
The blob-store recommendation rested on a premise that did not hold: shared-tier rows carry a null content column and a path pointer by design, episodic rows are summaries by construction rather than transcripts, and typical fact rows are a sentence or two, below the threshold at which the database externalizes values at all. With an application-level content cap the concern is bounded away, and the proposed cure is exactly the dual-write fragility the same review had correctly condemned elsewhere.
 View full size

Read figure text
DECLINED Change-data-capture Flips with a hosted multi-tenant offering, or a second and third genuine consumer of the memory change stream. | DECLINED External blob store Flips with a memory kind that stores large artifacts, for that kind only.
We record both with explicit adoption triggers rather than as doctrine: a hosted multi-tenant offering, or a second and third genuine consumer of the memory change stream, would flip the first; a memory kind that stores large artifacts would flip the second, for that kind only. A rejection that names the observable condition under which it reverses is a decision; one that does not is a preference.
10.3 Limitations and deferred scope
The tree is not a lattice. Single ancestry is the baseline’s central simplification, and real organizations violate it: people belong to several groups, project teams draw members from multiple departments, functional roles cut across the hierarchy, and regulated industries add jurisdictional scopes that are orthogonal to reporting lines. Insurance (a target vertical organized as line-of-business × function × jurisdiction) is inherently a lattice; manufacturing is the clean tree. Generalizing means replacing an ordered chain with a union over a set of scopes and defining precedence when two incomparable scopes conflict, which is a genuinely harder merge problem than Equation 2. The design does not foreclose it: every item is already scope-tagged and the resolver is a single self-contained component, so the change is localized to resolution and merge rather than being a schema rewrite.
Higher tiers are populated by humans, not learning. The read path is fully n-tier from day one, but the tiers are written asymmetrically: SESSION and USER automatically, GROUP and above by explicit human action. Automatically deciding that a personal pattern should become team or organizational canon (consensus thresholds, governance gates, revocation) is the hard part, and deferring it was what made an n-tier baseline tractable rather than a research project. Provenance and importance are recorded on every item from the first migration, because those are exactly the signals a promotion job would need.
Other deferrals. Daily-digest consolidation, a sensitivity classifier on write, the full administrative interface, and multi-tenancy (the deployment model is single-tenant per instance, so there is no tenant dimension in the schema). Each is listed so the boundary is unambiguous.
Related work
Agent memory frameworks. A cluster of systems now offers extraction, storage and recall of conversational memory with broadly similar type vocabularies (working, episodic, semantic, procedural) and a consolidation loop. This vocabulary has effectively become standard, and we adopt it. Where the present work differs is orthogonal to those systems rather than competitive with them: they are predominantly user-keyed, treating memory as a property of a principal, whereas the contribution here is that the owning scope is a first-class primitive that is simultaneously an authorization boundary, and that precedence direction is a function of memory type. A user-keyed store can be the extraction engine underneath an n-tier resolver; indeed one permissively licensed extraction library is retained as a fallback for exactly that layer. Frameworks that are tightly coupled to a particular orchestration runtime were rejected on integration grounds rather than on merit.
Knowledge representation. The shared tier adopts an open specification for structured markdown knowledge bundles: directory tree, frontmatter, index files, cross-references. Two properties made it a fit. It is a format rather than shipped software, so it introduces no dependency to patch in an air-gapped install; and it explicitly targets version control, which pairs with the commit-as-audit-record decision. We extend the specification in one respect: cross-references are typed from a controlled vocabulary (governs, depends-on, supersedes, owned-by), because untyped links give a structural file graph for free while a semantic knowledge graph is cheap to establish early and expensive to retrofit.
Consistency patterns. The write path is a textbook transactional outbox with a nightly reconciliation backstop. We note only that the outbox is deliberately change-data-capture shaped, so that if scale ever justifies the heavier transport, the migration replaces the transport rather than the model.
Filtered vector search. The requirement that entitlement be enforced inside graph traversal rather than as a post-filter is what pins the choice of vector backend. Systems that post-filter after approximate search over-fetch and lose recall precisely when the filter is selective, which is the normal case for per-user memory. A relational-extension backend remains selectable for small installations, behind an abstraction, since correctness does not depend on the choice; only recall under tight filters does.
Offline consolidation. Scheduled between-session reflection over an agent’s persistent memory has recently been productized. As argued in §8, its mechanical core (merge duplicates, prefer the most recent, prune the stale) is consolidation, which is present here; its distinctive addition is cross-episode synthesis. We adopt the review-gate pattern that accompanies it (a revised store the human may keep, edit or discard) and note that this coincides with the governance gate the organizational setting already required.
Conclusion
We have described a memory substrate for permissioned enterprise assistants built on two orthogonal axes. Scope places every memory in an organizational containment tree and simultaneously defines who may see it, so that no second authorization mechanism exists to drift out of sync with the first. Kind selects the direction in which conflicts resolve, so that a personal preference can override an organizational default while organizational policy overrides a personal note: an asymmetry that a scope-only model cannot express and that we found to be the correctness bug in the predecessor design. On top of these, the pointer-not-cache invariant makes an entire class of staleness failures structurally impossible by refusing to let authority memory hold values at all.
Two further results seem worth carrying to other systems. First, the storage split: personal and organizational memory have opposite profiles on churn, authorship, lifetime and audit requirement, and insisting on one physical store means serving one of them badly; uniformity belongs at the interface. Second, the defect taxonomy: five failures that each defeated a stated guarantee while tests passed, all of them at seams between locally correct components. Acceptance tests written against the claim, with data constructed so the claim fails when the mechanism is removed, found what component tests could not.
The immediate next step is the lattice: replacing single ancestry with overlapping scopes, which turns chain resolution into a set union and forces a precedence rule for incomparable scopes. After that, the promotion problem: deciding, with consensus evidence and a governance gate, when something a person knows should become something their organization knows. The present design is deliberately the substrate for that question rather than an answer to it.
 View full size

Read figure text
THE TRANSFERABLE LESSON Acceptance tests written against the claim, with data constructed so the claim fails when the mechanism is removed, found what component tests could not.
Appendix A: Core schema
| Column | Type | Meaning |
|---|---|---|
| id | uuid | Primary key. Also the vector point identifier (1:1). |
| scope_type | varchar(16) | session | user | group | org, check-constrained. |
| scope_id | text | The owner: a user, a group, or a session. |
| memory_type | varchar(32) | Storage layer: semantic, episodic. |
| kind | varchar(32) | Drives merge precedence (Equation 2). |
| subject_key | text | Normalized topic key; collides for dedup (write) and conflict (read). |
| content | text | The fact text. Null for shared-tier rows, which carry a path instead. |
| okf_path | text | For shared tiers: the path into the versioned bundle. |
| importance | float | Salience in [0, 1]; resists budget truncation. |
| confidence | float | Extractor confidence; reinforced by repetition. |
| source_chat_event_id | text | Provenance; part of the uniqueness constraint. |
| embedding_ref | text | sha256(content): a content/version key, not the point id. |
| pinned | bool | Explicit pin; bypasses the budget and decay. |
| acl | jsonb | {user_ids, user_group_ids, is_public}: the contract with the read path. |
| expires_at | timestamptz | Optional expiry, used by consolidation. |
| created_at / updated_at | timestamptz | Recency signal and same-scope tie-break. |
Indexes: (scope_type, scope_id); kind; (scope_type, scope_id, subject_key); and the uniqueness constraint (source_chat_event_id, scope_type, scope_id, kind, embedding_ref).
Supporting tables: memory_episode (session summaries: summary, topic, outcome, entities); memory_profile (one row per scope: standing instructions); memory_policy (per-scope tuning: budget shares, enabled kinds, decay, ranking weights; the customizability surface, so that two verticals tune one engine without code changes); memory_audit (actor, action, item, reason); and memory_outbox (item, operation, status, attempts, carried vector). One existing table is extended: user_group gains parent_group_id (the self-referential key that forms the tree) and okf_dir (the bundle mapping).
Two subtleties that cost time and are worth flagging. embedding_ref is not the point identifier; confusing the two breaks reconciliation. And the ACL is nested JSON whose exact key shape is a contract between writer and reader: a disagreement there is not a crash, it is a silent leak, which is why it is the subject of an explicit review check rather than only a test.
Appendix B: Vector point layout
 View full size

Read figure text
id = a1b2c3d4-0000-0000-0000-000000000001 # == memory_item.id vector = { "text-dense": [0.013, -0.041,... 4096 floats...], # COSINE "text-sparse": {indices: [...], values: [...]} } # BM25 + IDF payload = { "scope_type": "USER", "scope_id": "11111111-1111-1111-1111-111111111111", "kind": "preference", "subject_key":"answer_length", "importance": 0.6, "pinned": false, "updated_at": 1753158000.0, "acl": { "user_ids": ["1111..."], "user_group_ids": [], "is_public": false }, "text": "prefers brief answers" # denormalized: no round-trip on the read path }
Payload indexes exist on scope_type, scope_id, kind, memory_type, acl.user_ids, acl.user_group_ids, acl.is_public, pinned and importance, so that filters execute inside graph traversal. The denormalized text is a read optimization and not a change of ownership: the row and the versioned file remain the sources of truth, and the payload copy is rebuilt with the point.
Appendix C: End-to-end walkthrough
MONDAY A preference is captured Ramesh, in session A: “From now on always give me brief answers and use metric units.” The turn completes and the response returns immediately; an extraction job is enqueued. The worker claims the event, extracts F1 and F2, embeds both once, finds no same-subject neighbour for either, and commits two rows each with a pending outbox row. Seconds later the drainer upserts two points and marks the rows done. Had the event been delivered twice, the second insert would have conflicted and no second row (and no orphan outbox row) would exist.
MEANWHILE The leak bait
In a separate conversation Meena stores F4, a near-paraphrase of F1, at her own scope with the Legal group’s ACL. Its vector sits adjacent to Ramesh’s.
ALSO STORED The group authority
A curator commits the Line 3 torque concept: kind authority, subject torque, a resource pointer to SOP-114, and a value-free body. The linter rejects any version of this file that states a torque number. The indexer derives a stable identifier from the frontmatter, writes the point (with the pointer in the payload) and the Postgres pointer row. Separately, Ramesh once mumbled a guess, stored at his user scope with the same conflict key.
THURSDAY Recall
New session B: “How should you format answers for me?”
1. chain = [SESSION:sess_B, USER:1111..., GROUP:42, GROUP:30, GROUP:20, ORG:10]2. embed = one query vector3. search = ACL filter ORs {is_public, user_ids > 1111..., group_ids > 42,30,20,10}
Meena's F4 is near in vector space but matches no principal
-> returned scope_ids = { 1111... } Meena ABSENT. [C2]
hits = F1, F24. rank = relevance dominates; both on-topic5. merge = no shared (kind, subject) among them -> both survive6. budget = USER cap 3 -> both kept7. render = "## Relevant memory ... - [preference] prefers brief answers ..."FRIDAY The conflict “What’s the torque spec on Line 3?” Now two items share the key (authority, torque): Ramesh’s personal guess at chain index 1 and the group pointer at index 2. Authority resolves highest-wins, so the pointer survives and the guess is dropped as the conflict loser; and because the budget runs after merge, no amount of high-relevance competition at the group tier can evict the winner first. What is injected names SOP-114 and states no number; the pointer then resolves through document retrieval to the current version. When the standard is revised, the same question yields the new value with no memory write anywhere in the system, which is claim C4, and the reason authority memory is forbidden from holding values in the first place.
Appendix D: Configuration surface
All behaviour is tunable through a MEMORY_* configuration namespace with global defaults, and overridable per scope through a policy row, which is what lets two verticals with very different knowledge shapes tune one engine without code changes.
| Dimension | Expressed as | Default |
|---|---|---|
| Master gate | MEMORY_ENABLED | off |
| Which tiers are active | Enabled scope types | all |
| Per-tier injection budget | Budget shares | 4 / 3 / 2 / 1 |
| Ranking weights | wrel, wrec, wimp | 0.8 / 0.1 / 0.1 |
| Recency half-life | Decay window | 30 days |
| Dedup threshold | Cosine τ | 0.92 |
| Read deadline | Wall clock | 800 ms |
| Drain attempts before retirement | Counter | 5 |
| Content cap | Application-layer limit | 4 KB |
| Retention | Per-tier expiry windows | per policy |
| Database | MEMORY_DB_URL | the existing database |
The default for the database connection deserves a note: it points at the existing database, so a customer requiring an isolated memory database (independent sizing, backups, vacuum tuning) obtains it as a deployment-time connection-string decision with zero code change. That pattern (make the isolation boundary a configuration value rather than an architecture) recurs throughout and is the main way this design keeps its options open without carrying their cost.